latent-v1-8b0d3f9-6e874509-47646604
completed —
Hypothesis
A variational autoencoder over codec programs, trained on the 2,681 training icons and their compositions, keeps information in its 64-dimensional latent. Pass requires (1) reconstruction pixel error on the 339 validation icons below the error of the single prior-mean decode, paired, with the 95% interval on the reduction excluding zero; (2) at least 29 of 32 prior samples distinct. Reported without a criterion: reconstruction against the nearest training icon, interpolation and prior-sample sheets, and decode latency.
Visual output
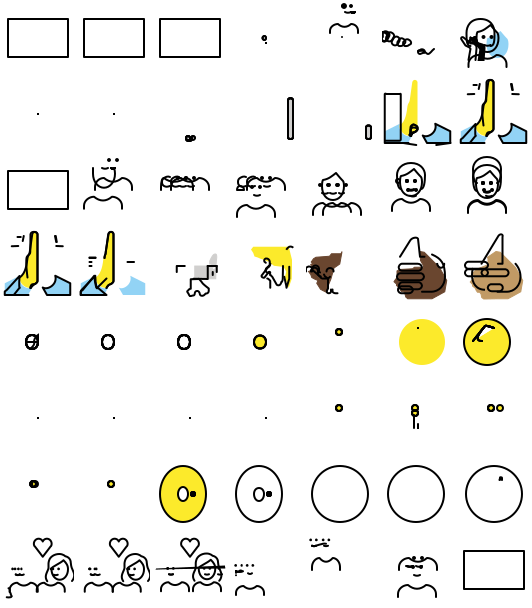
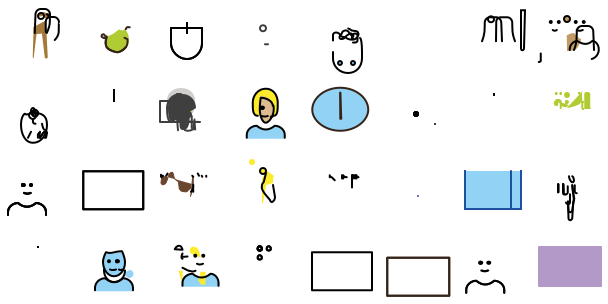

Written result
Hypothesis. A variational autoencoder over codec programs, trained on the 2,681 training icons and their compositions, keeps information in its 64-dimensional latent. Pass requires (1) reconstruction pixel error on the 339 validation icons below the error of the single prior-mean decode, paired, with the 95% interval on the reduction excluding zero; (2) at least 29 of 32 prior samples distinct. Reported without a criterion: reconstruction against the nearest training icon, interpolation and prior-sample sheets, and decode latency.
| measure | value |
|---|---|
| validation icons | 339 |
| reconstruction pixel error | 0.1823 [0.1752, 0.1894] |
| nearest training icon pixel error | 0.0897 |
| prior-mean decode pixel error (control) | 0.1724 |
| error reduction, own latent vs prior mean | -0.0100 [-0.0134, -0.0065] |
| exact reconstructions | 0.000 |
| prior samples distinct / rendered | 32 / 32 of 32 |
| prior samples, median pixel distance to nearest training icon | 0.0533 |
| parameters | 10,114,082 |
| train seconds | 3114 |
| decode ms per icon (graph, batch 1) | 357.3 |
Sheets: reconstructions.png, interpolations.png, prior-samples.png.
State transitions
- running2026-09-28T01:06:16Z
- completed2026-09-28T01:59:17Z
Run record
Verbatim from runs/latent-v1-8b0d3f9-6e874509-47646604/run.yaml, the record committed before launch.
schema_version
2
run_id
latent-v1-8b0d3f9-6e874509-47646604
state
completed
planned_at
2026-09-28T01:06:16Z
hypothesis
A variational autoencoder over codec programs, trained on the 2,681 training icons and their compositions, keeps information in its 64-dimensional latent. Pass requires (1) reconstruction pixel error on the 339 validation icons below the error of the single prior-mean decode, paired, with the 95% interval on the reduction excluding zero; (2) at least 29 of 32 prior samples distinct. Reported without a criterion: reconstruction against the nearest training icon, interpolation and prior-sample sheets, and decode latency.
parent_run
r2s-full-v7-systems
git_commit
8b0d3f99a1d76a589aaaf5f1ee92315ad9548ea9
dirty_patch_sha256
config_sha256
6e874509391a40b7…config
configs/latent/latent-v1.yaml
config_resolved
model
image_size
144
d_model
256
heads
8
encoder_layers
2
decoder_layers
6
feedforward
1024
dropout
0.1
metric
true
fourier
10
order
path
latent
latent_dim
64
memory_tokens
16
encoder_layers
3
beta
1.0
beta_warmup_fraction
0.3
free_bits
0.1
input_dropout
0.25
training
steps
30000
batch_size
32
learning_rate
0.0005
weight_decay
0.01
warmup_steps
1000
seed
7001
eval_every
2000
eval_icons
64
train_icons
None
evaluate_on_train
false
augment_variants
0
augment_seed
9001
augment_mirror
0.5
augment_max_shift
48
augment_colour
0.5
augment_online
true
compose_probability
0.5
compose_parts
4
augment_original
0.1
loader_workers
12
extra_training
bf16
true
dataset
pilot_config
configs/learning/openmoji-g1-geometric-gate-v16.yaml
cache_sha256
476466042da98d72…train_icons
2681
evaluated_on
primary/validation
seed
7001
determinism
seeded; cuDNN and SDPA kernels not forced deterministic
model_parameters
10114082
command
.venv/bin/python -m mojidiff.learning.latent --config configs/latent/latent-v1.yaml
outputs
run_dir
runs/latent-v1-8b0d3f9-6e874509-47646604
checkpoints
/home/dev/.cache/mojidiff/runs/latent-v1-8b0d3f9-6e874509-47646604
completed_at
2026-09-28T01:59:17Z
resource
device
NVIDIA GeForce RTX 4080
torch_version
2.14.0a0+4fdf77b940.nv26.08
cuda_version
13.4
python_version
3.12.3
peak_vram_gib
5.323237895965576
train_seconds
3114.212936943979
inference_ms_per_icon
357.2574824793264
inference_p95_ms_per_icon
357.38330194726586
icons_per_second
2.79910162569616
decoder
fast_decode.GraphDecoder, float32, batch 1, from a latent
decoder_calls
273
excludes
rasterising the output SVG
note
measured while other GPU work may be running; see gpu load at the time
baselines
nearest_training_icon_pixel_error
0.08973124639576185
note
retrieval stores every training icon; the latent stores 64 numbers
result
icons
339
reconstruction_pixel_error
0.1823458152666556, 0.1751978503806643, 0.1894197406431325
nearest_training_icon_pixel_error
0.08973124639576185, 0.0848205749792233, 0.09466393787711656
prior_mean_decode_pixel_error
0.17238419489786688, 0.16538361558459896, 0.1797671404983134
latent_minus_prior_mean_error_reduction
-0.009961620368788728, -0.01343069137747133, -0.006493465149099319
exact_reconstruction_rate
0.0
prior_samples
count
32
distinct
32
rendered
32
median_pixel_distance_to_nearest_training_icon
0.05325271561741829
selected_step
16000