latent-v3-blind-e254c16-9c7db490-47646604
completed —
Hypothesis
Blind to earlier coordinates, the decoder must take geometry from the latent. Pass, against latent-v2 on the 339 validation icons: (1) at most 15% of reconstructed paths span under half a unit (latent-v2 57%); (2) reconstruction pixel error improves on latent-v2's, paired, interval excluding zero, to 0.140 or less; (3) prior samples all distinct. The earlier criteria are kept below and still reported: A variational autoencoder over codec programs, trained on the 2,681 training icons and their compositions, keeps information in its 64-dimensional latent. Pass requires (1) reconstruction pixel error on the 339 validation icons below the error of the single prior-mean decode, paired, with the 95% interval on the reduction excluding zero; (2) at least 29 of 32 prior samples distinct. Reported without a criterion: reconstruction against the nearest training icon, interpolation and prior-sample sheets, and decode latency.
Visual output
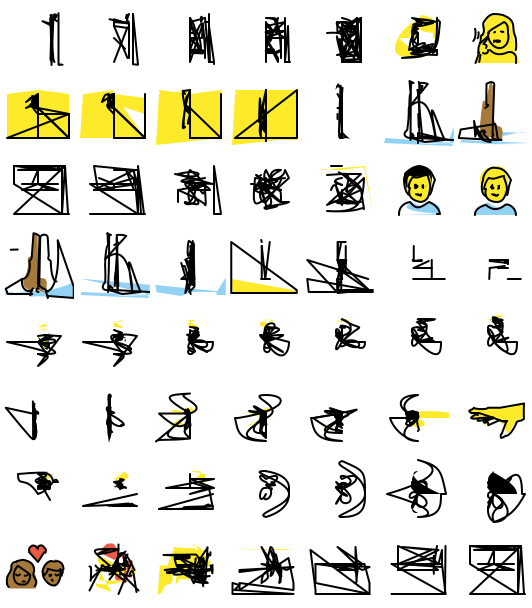
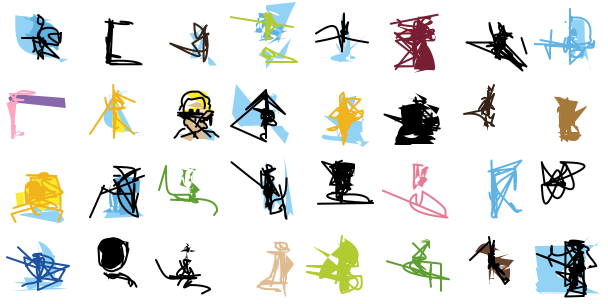

Written result
Hypothesis. Blind to earlier coordinates, the decoder must take geometry from the latent. Pass, against latent-v2 on the 339 validation icons: (1) at most 15% of reconstructed paths span under half a unit (latent-v2 57%); (2) reconstruction pixel error improves on latent-v2's, paired, interval excluding zero, to 0.140 or less; (3) prior samples all distinct. The earlier criteria are kept below and still reported: A variational autoencoder over codec programs, trained on the 2,681 training icons and their compositions, keeps information in its 64-dimensional latent. Pass requires (1) reconstruction pixel error on the 339 validation icons below the error of the single prior-mean decode, paired, with the 95% interval on the reduction excluding zero; (2) at least 29 of 32 prior samples distinct. Reported without a criterion: reconstruction against the nearest training icon, interpolation and prior-sample sheets, and decode latency.
| measure | value |
|---|---|
| validation icons | 339 |
| reconstruction pixel error | 0.1733 [0.1667, 0.1802] |
| nearest training icon pixel error | 0.0897 |
| prior-mean decode pixel error (control) | 0.1932 |
| error reduction, own latent vs prior mean | 0.0198 [0.0156, 0.0242] |
| exact reconstructions | 0.000 |
| prior samples distinct / rendered | 32 / 32 of 32 |
| prior samples, median pixel distance to nearest training icon | 0.0958 |
| parameters | 10,114,082 |
| train seconds | 3423 |
| decode ms per icon (graph, batch 1) | 579.3 |
Sheets: reconstructions.png, interpolations.png, prior-samples.png.
State transitions
- running2026-09-29T12:22:11Z
- completed2026-09-29T13:20:52Z
Run record
Verbatim from runs/latent-v3-blind-e254c16-9c7db490-47646604/run.yaml, the record committed before launch.
9c7db490a2fe6b32…476466042da98d72…