prior-m2-finetune-26f873a-32icons-9b9b1699
completed —
Measured behaviour
Table view
| optimizer step | model |
|---|---|
| 0 | 0.3788 |
| 25 | 0.2925 |
| 50 | 0.2776 |
| 75 | 0.2691 |
| 100 | 0.2662 |
| 125 | 0.2610 |
| 150 | 0.2596 |
| 175 | 0.2589 |
| 200 | 0.2546 |
| 225 | 0.2556 |
| 250 | 0.2527 |
| 275 | 0.2502 |
| 300 | 0.2619 |
| 325 | 0.2520 |
| 350 | 0.2487 |
| 375 | 0.2529 |
| 400 | 0.2673 |
| 425 | 0.2584 |
| 450 | 0.2558 |
| 475 | 0.2561 |
| 500 | 0.2589 |
Measured result
Verbatim from the run's summary.json.
adapter_sha256
8bd1241958ce3ceb…checks
clip_gain_over_control
true
codec_valid_rate
false
memorisation
true
reference_top1_rate
false
clip_to_caption
mean
0.22395725516562767
median
0.22379297018051147
n
47
clip_to_reference
mean
0.838817224857655
median
0.848332941532135
n
47
closed_svg_rate
0.734375
codec_valid_rate
0.6875
config_sha256
4a3c076649e7b6a6…control
clip_to_reference_mean
0.8366116285324097
control_clip_to_reference_mean
0.7968365723888079
control_codec_valid_rate
0.046875
control_reference_top1_rate
None
control_rows_sha256
ca33f9adbb2b2fc0…gain_ci95
0.019133694159487884, 0.058518097860117746
icons_improved
10
mean_gain
0.03977505614360174
paired_icons
12
report_root
reports/learning/prior-m2-control
criteria
clip_gain_over_control_ci_excludes_zero
true
max_memorised_exactly
0
min_codec_valid_rate
0.8
min_reference_top1_rate
0.25
drawings
64
ended_rate
0.734375
failures
encode:control coordinate is outside -8..96 and clamping is disabled
1
encode:stroke value is outside the configured vocabulary: '#e27019'
1
no_closed_svg
17
pack:program needs 139 packed segments but capacity is 128
1
generation
max_new_tokens
4096
seconds_per_drawing
40.81928221164071
icons
32
median_tokens
1848.0
memorised_exactly
0
mode
finetune
model
fine_tuned
true
parameters
1898644288
revision
b1485b2fa6dfa1287294f269f5fb618e03d52d7c
source
Qwen/Qwen3.5-2B-Base
trainable_parameters
16819200
predeclared_outcome
falsified
raw_render_rate
0.734375
reference_rank
chance_top1
0.03125
mean
10.297872340425531
scored
47
top1_rate
0.09375
top5_rate
0.296875
rows_sha256
2e085f3614b36e54…samples_per_icon
2
schema_version
1
sheet_sha256
7f41fd23497819dc…study_version
prior-m2-finetune
timing
load_seconds
4.754281700006686
training
excluded_held_over_max_tokens
16
excluded_train_over_max_tokens
1229
held_out_icons
16
held_out_nll
0.24874354906605176
initial_held_out_nll
0.3787819057411045
max_tokens
2048
peak_vram_gib
6.83345365524292
selected_step
350
sequences_per_step
8
steps_run
500
train_icons
1452
train_seconds
1434.669112641015
Visual output
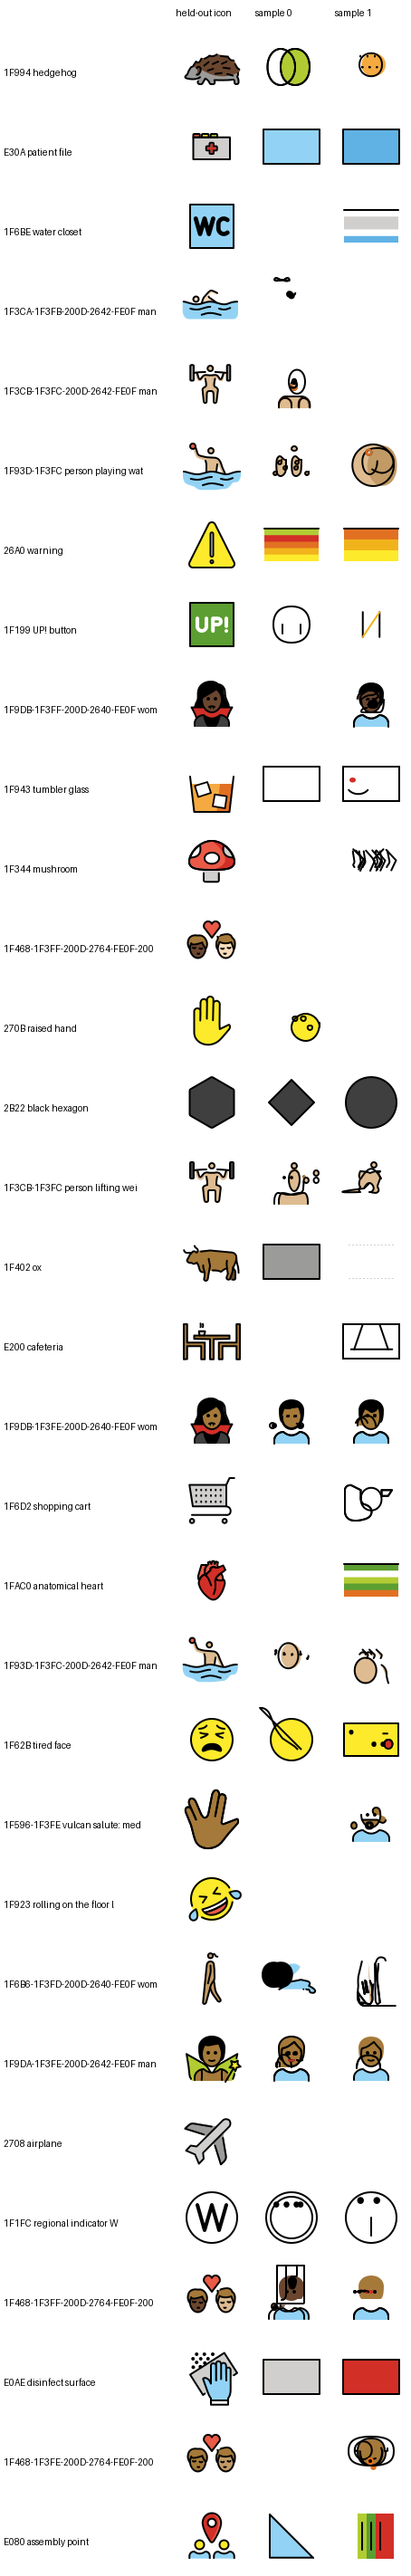
State transitions
- planned2026-09-21T14:48:04Z
- completed2026-09-21T16:33:16Ztrained on the 1,452 training icons under 2,048 tokens (1,229 excluded), held-out likelihood 0.379 to 0.249 nats a token, selected at step 350; 47 of 64 drawings close (control 18), 44 enter the typed codec (control 3), CLIP-to-reference 0.839 over the 47 (control 0.798 over 17), paired gain over the 17 pairable icons +0.040 with a 95% interval of +0.019 to +0.059; the right icon first for 6 of 64 (chance 2), top five for 19, mean rank 10.3 of 32; no training icon reproduced; 40.8 s a drawing
Run record
This run has no run.yaml. What follows is the identity and configuration carried by its rows in state/runs.jsonl, the append-only registry.
run_id
prior-m2-finetune-26f873a-32icons-9b9b1699
config
configs/learning/prior-m2-finetune.yaml
outputs
adapter
data/processed/prior/prior-m2-finetune/adapter.zip
adapter_sha256
8bd1241958ce3ceb…report_root
reports/learning/prior-m2-finetune