r2s-cur-d02-dec8-s120k-53b3108-f17a6a39-47646604
completed —
Hypothesis
With dropout 0.2 and 120k steps, 8 decoder layers transcribe validation renders better than v9. Pass requires the paired 95% bootstrap interval on the per-icon reduction in mean 72 px pixel error on the 339 validation renders to exclude zero against each normal v9 run (RTX 4080 original, H100 rerun, B300 seeds 2 and 3). Its greedy latency on the RTX 4080 is recorded.
Visual output
Written result
Hypothesis. With dropout 0.2 and 120k steps, 8 decoder layers transcribe validation renders better than v9. Pass requires the paired 95% bootstrap interval on the per-icon reduction in mean 72 px pixel error on the 339 validation renders to exclude zero against each normal v9 run (RTX 4080 original, H100 rerun, B300 seeds 2 and 3). Its greedy latency on the RTX 4080 is recorded.
Result
| measure | value |
|---|---|
| icons evaluated | 339 (primary/validation) |
| model pixel error, mean [95% CI] | 0.0706 [0.0657, 0.0756] |
| model pixel error, median | 0.0647 |
| exact program rate | 0.006 |
| rendered rate | 1.000 |
| blank canvas pixel error | 0.1720 |
| nearest training icon pixel error | 0.0897 [0.0848, 0.0947] |
| error reduction vs nearest icon | 0.0191 [0.0152, 0.0230] |
| icons where model beats nearest icon | 260 |
| CLIP top-1, model greedy (32 Gate N icons) | 0.812 |
| CLIP top-1, nearest training icon | 0.344 |
| CLIP top-1, OmniSVG 4B zero-shot (Gate N) | 0.609 |
Resources
| measure | value |
|---|---|
| device | NVIDIA B300 SXM6 AC |
| parameters | 11,132,706 |
| train seconds | 5830 |
| peak VRAM GiB | 5.548205375671387 |
| latency ms/icon, batch 1, median | 3957.2 |
| latency ms/icon, batch 1, p95 | 3964.6 |
| throughput ms/icon, batch 64 | 128.2 |
| model calls per icon (decoding) | 686.0 |
| torch / CUDA | 2.14.1+cu130 / 13.0 |
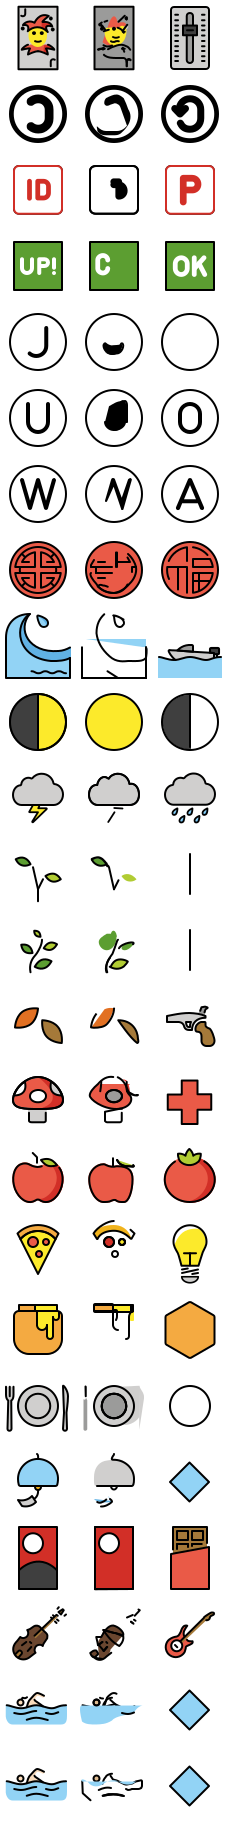
Latency covers encoding and decoding to a validated token program; it excludes rasterising the SVG. Samples: samples.png, rows are reference, model, nearest training icon.
State transitions
- running2026-10-30T18:18:03Z
- completed2026-10-30T19:58:31Z
Run record
Verbatim from runs/r2s-cur-d02-dec8-s120k-53b3108-f17a6a39-47646604/run.yaml, the record committed before launch.
schema_version
2
run_id
r2s-cur-d02-dec8-s120k-53b3108-f17a6a39-47646604
state
completed
planned_at
2026-10-30T18:18:03Z
hypothesis
With dropout 0.2 and 120k steps, 8 decoder layers transcribe validation renders better than v9. Pass requires the paired 95% bootstrap interval on the per-icon reduction in mean 72 px pixel error on the 339 validation renders to exclude zero against each normal v9 run (RTX 4080 original, H100 rerun, B300 seeds 2 and 3). Its greedy latency on the RTX 4080 is recorded.
parent_run
r2s-cur-d02-s120k
git_commit
53b3108784dee11612fef24a88aa39bd393843c8
dirty_patch_sha256
config
configs/render2svg/cur-d02-dec8-s120k.yaml
config_sha256
f17a6a3920b93710…config_resolved
model
image_size
144
d_model
256
heads
8
encoder_layers
2
decoder_layers
8
feedforward
1024
dropout
0.2
metric
true
fourier
10
order
path
sources
0
training
steps
120000
batch_size
32
learning_rate
0.0005
weight_decay
0.01
warmup_steps
1000
seed
7001
eval_every
2000
eval_icons
64
train_icons
None
evaluate_on_train
false
augment_variants
0
augment_seed
9001
augment_mirror
0.5
augment_max_shift
48
augment_colour
0.1
augment_online
true
compose_probability
0.5
compose_parts
4
augment_original
0.1
loader_workers
16
extra_training
bf16
true
final_eval_icons
339
clip_icons
32
dataset
pilot_config
configs/learning/openmoji-g1-geometric-gate-v16.yaml
cache_sha256
476466042da98d72…train_icons
2681
augmented_variants
0
extra_training
None
augmented_sha256
None
evaluated_on
primary/validation
seed
7001
determinism
seeded; cuDNN and SDPA kernels not forced deterministic
model_parameters
11132706
command
.venv/bin/python -m mojidiff.learning.render2svg --config configs/render2svg/cur-d02-dec8-s120k.yaml
outputs
run_dir
runs/r2s-cur-d02-dec8-s120k-53b3108-f17a6a39-47646604
checkpoints
/home/eai-jdkxz/eai-team11/mojidiff/cache/runs/r2s-cur-d02-dec8-s120k-53b3108-f17a6a39-47646604
notes
completed_at
2026-10-30T19:58:31Z
resource
device
NVIDIA B300 SXM6 AC
torch_version
2.14.1+cu130
cuda_version
13.0
python_version
3.12.3
peak_vram_gib
5.548205375671387
train_seconds
5829.999086665979
inference_ms_per_icon
3957.158368488308
inference_p95_ms_per_icon
3964.5562659716234
icons_per_second
0.2527065906594015
batched_ms_per_icon
128.24326148438558
batched_icons_per_call
64
excludes
rendering the output SVG to pixels
baselines
blank_canvas_pixel_error
0.1720480552069557
nearest_training_icon_pixel_error
0.08973124639576185
gate_n_omnisvg_zero_shot_top1
0.609375
nearest_training_icon_clip_top1
0.34375
result
icons
339
model_pixel_error
0.07060982561604996, 0.0656904120237529, 0.07564048579114084
model_pixel_error_median
0.06469175964593887
exact_program_rate
0.0058997050147492625
rendered_rate
1.0
blank_pixel_error
0.1720480552069557
selected_step
36000
nearest_training_icon_pixel_error
0.08973124639576185, 0.0848205749792233, 0.09466393787711656
model_minus_baseline_error_reduction
0.019121420779711892, 0.01518248796764482, 0.023002695114370527
icons_model_beats_baseline
260
clip_retrieval
model_greedy
top1_rate
0.8125
top5_rate
0.96875
mean_rank
1.8125
clip_to_reference_mean
0.9331411644816399
chance_top1
0.03125
icons
32
nearest_training_icon
top1_rate
0.34375
top5_rate
0.59375
mean_rank
7.40625
clip_to_reference_mean
0.8630617223680019
chance_top1
0.03125
icons
32
gate_n_omnisvg_zero_shot_top1
0.609375
gate_n_omnisvg_best_of_12_top1
0.828125
model_calls_per_icon
686