r2s-cur-d02-lr3-s6-8e367a7-68fa0e07-47646604
completed —
Hypothesis
With a learning rate of 3e-4 instead of 5e-4 and everything else as dropout 0.2 at 60k steps, the model transcribes the 339 validation renders better than the dropout-0.2 run of the same seed. Judged over seeds 7001-7008: the mean seed-matched difference with a bootstrap interval over seeds excluding zero.
Visual output
Written result
Hypothesis. With a learning rate of 3e-4 instead of 5e-4 and everything else as dropout 0.2 at 60k steps, the model transcribes the 339 validation renders better than the dropout-0.2 run of the same seed. Judged over seeds 7001-7008: the mean seed-matched difference with a bootstrap interval over seeds excluding zero.
Result
| measure | value |
|---|---|
| icons evaluated | 339 (primary/validation) |
| model pixel error, mean [95% CI] | 0.0796 [0.0744, 0.0850] |
| model pixel error, median | 0.0718 |
| exact program rate | 0.006 |
| rendered rate | 1.000 |
| blank canvas pixel error | 0.1720 |
| nearest training icon pixel error | 0.0897 [0.0848, 0.0947] |
| error reduction vs nearest icon | 0.0102 [0.0056, 0.0146] |
| icons where model beats nearest icon | 209 |
| CLIP top-1, model greedy (32 Gate N icons) | 0.531 |
| CLIP top-1, nearest training icon | 0.344 |
| CLIP top-1, OmniSVG 4B zero-shot (Gate N) | 0.609 |
Resources
| measure | value |
|---|---|
| device | NVIDIA B300 SXM6 AC |
| parameters | 9,025,826 |
| train seconds | 2640 |
| peak VRAM GiB | 4.388660430908203 |
| latency ms/icon, batch 1, median | 4564.2 |
| latency ms/icon, batch 1, p95 | 4575.3 |
| throughput ms/icon, batch 64 | 130.8 |
| model calls per icon (decoding) | 937.0 |
| torch / CUDA | 2.14.1+cu130 / 13.0 |
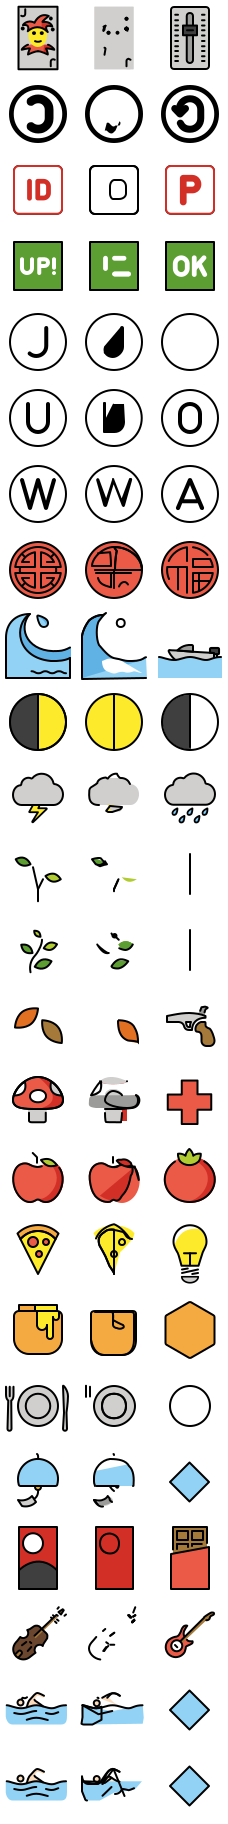
Latency covers encoding and decoding to a validated token program; it excludes rasterising the SVG. Samples: samples.png, rows are reference, model, nearest training icon.
State transitions
- running2026-10-31T01:46:10Z
- completed2026-10-31T02:33:11Z
Run record
Verbatim from runs/r2s-cur-d02-lr3-s6-8e367a7-68fa0e07-47646604/run.yaml, the record committed before launch.
schema_version
2
run_id
r2s-cur-d02-lr3-s6-8e367a7-68fa0e07-47646604
state
completed
planned_at
2026-10-31T01:46:10Z
hypothesis
With a learning rate of 3e-4 instead of 5e-4 and everything else as dropout 0.2 at 60k steps, the model transcribes the 339 validation renders better than the dropout-0.2 run of the same seed. Judged over seeds 7001-7008: the mean seed-matched difference with a bootstrap interval over seeds excluding zero.
parent_run
r2s-cur-dropout02
git_commit
8e367a70bf39659e61188db527635cf15cc6a554
dirty_patch_sha256
5b6869fc64bc599d…config
configs/render2svg/cur-d02-lr3-s6.yaml
config_sha256
68fa0e07f720e83f…config_resolved
model
image_size
144
d_model
256
heads
8
encoder_layers
2
decoder_layers
6
feedforward
1024
dropout
0.2
metric
true
fourier
10
order
path
sources
0
training
steps
60000
batch_size
32
learning_rate
0.0003
weight_decay
0.01
warmup_steps
1000
seed
7006
eval_every
2000
eval_icons
64
train_icons
None
evaluate_on_train
false
augment_variants
0
augment_seed
9006
augment_mirror
0.5
augment_max_shift
48
augment_colour
0.1
augment_online
true
compose_probability
0.5
compose_parts
4
augment_original
0.1
loader_workers
16
extra_training
bf16
true
final_eval_icons
339
clip_icons
32
dataset
pilot_config
configs/learning/openmoji-g1-geometric-gate-v16.yaml
cache_sha256
476466042da98d72…train_icons
2681
augmented_variants
0
extra_training
None
augmented_sha256
None
evaluated_on
primary/validation
seed
7006
determinism
seeded; cuDNN and SDPA kernels not forced deterministic
model_parameters
9025826
command
.venv/bin/python -m mojidiff.learning.render2svg --config configs/render2svg/cur-d02-lr3-s6.yaml
outputs
run_dir
runs/r2s-cur-d02-lr3-s6-8e367a7-68fa0e07-47646604
checkpoints
/home/eai-jdkxz/eai-team11/mojidiff/cache/runs/r2s-cur-d02-lr3-s6-8e367a7-68fa0e07-47646604
notes
completed_at
2026-10-31T02:33:11Z
resource
device
NVIDIA B300 SXM6 AC
torch_version
2.14.1+cu130
cuda_version
13.0
python_version
3.12.3
peak_vram_gib
4.388660430908203
train_seconds
2640.3972900349763
inference_ms_per_icon
4564.219555497402
inference_p95_ms_per_icon
4575.25065401569
icons_per_second
0.21909550753217905
batched_ms_per_icon
130.76256285967247
batched_icons_per_call
64
excludes
rendering the output SVG to pixels
baselines
blank_canvas_pixel_error
0.1720480552069557
nearest_training_icon_pixel_error
0.08973124639576185
gate_n_omnisvg_zero_shot_top1
0.609375
nearest_training_icon_clip_top1
0.34375
result
icons
339
model_pixel_error
0.07955320501201416, 0.07440158898992309, 0.08499835891722789
model_pixel_error_median
0.07178498059511185
exact_program_rate
0.0058997050147492625
rendered_rate
1.0
blank_pixel_error
0.1720480552069557
selected_step
48000
nearest_training_icon_pixel_error
0.08973124639576185, 0.0848205749792233, 0.09466393787711656
model_minus_baseline_error_reduction
0.010178041383747704, 0.005617069288572966, 0.014648510966425766
icons_model_beats_baseline
209
clip_retrieval
model_greedy
top1_rate
0.53125
top5_rate
0.84375
mean_rank
3.84375
clip_to_reference_mean
0.9088644105941057
chance_top1
0.03125
icons
32
nearest_training_icon
top1_rate
0.34375
top5_rate
0.59375
mean_rank
7.40625
clip_to_reference_mean
0.8630617223680019
chance_top1
0.03125
icons
32
gate_n_omnisvg_zero_shot_top1
0.609375
gate_n_omnisvg_best_of_12_top1
0.828125
model_calls_per_icon
937