MojiDiff

← experiments

vt-v2-c16-0f4d5de-1497d4b5-47646604

completed —

Hypothesis

A variational transcriber - v9 whose 18 x 18 stem grid passes through a per-cell Gaussian latent (c = 16 channels) held at a KL budget of C = 2,000 nats per icon - keeps v9's persistent spatial record of what is still undrawn and so reconstructs held-out icons from its posterior mean close to v9, while its latent is smooth at the posterior scale. Pass, on the first 339 validation icons, IEEE float32 (TF32 off) greedy decoding, 72 px pixel error, bootstrap intervals, all comparisons paired, requires A1 and A3; A2 is a collapse check. (A1) reconstruction from mu is non-inferior to v9 re-decoded in float32 on the same icons - the upper 95% bound of (VT - v9) is at most +0.015 - and beats the nearest training render or its mirror (every model trains with mirrors), the 95% interval on the reduction excluding zero. (A2) held-out KL within [0.8C, 1.2C] = [1,600, 2,400] nats per icon with beta above its floor of 1e-4; the controller enforces this band, so it detects collapse and is not evidence of anything else. (A3) decoding one posterior sample instead of mu costs at most 0.010 pixel error, paired mean. Reported without a criterion: the z = 0 decode, N(0, I) samples as the prior-hole control (ink coverage, distinct, rendered), 8 lerp strips of posterior means (a canvas dissolve), graph-decoder latency. Decision: A1 and A3 pass - fit the flow prior (arm 3, lfp-v1). A1 fails - run once more at c = 16 under a new run identity; a second failure stops the canvas line.

Visual output
interpolations
interpolations.png
prior-samples
prior-samples.png
reconstructions
reconstructions.png

Written result

Hypothesis. A variational transcriber - v9 whose 18 x 18 stem grid passes through a per-cell Gaussian latent (c = 16 channels) held at a KL budget of C = 2,000 nats per icon - keeps v9's persistent spatial record of what is still undrawn and so reconstructs held-out icons from its posterior mean close to v9, while its latent is smooth at the posterior scale. Pass, on the first 339 validation icons, IEEE float32 (TF32 off) greedy decoding, 72 px pixel error, bootstrap intervals, all comparisons paired, requires A1 and A3; A2 is a collapse check. (A1) reconstruction from mu is non-inferior to v9 re-decoded in float32 on the same icons - the upper 95% bound of (VT - v9) is at most +0.015 - and beats the nearest training render or its mirror (every model trains with mirrors), the 95% interval on the reduction excluding zero. (A2) held-out KL within [0.8C, 1.2C] = [1,600, 2,400] nats per icon with beta above its floor of 1e-4; the controller enforces this band, so it detects collapse and is not evidence of anything else. (A3) decoding one posterior sample instead of mu costs at most 0.010 pixel error, paired mean. Reported without a criterion: the z = 0 decode, N(0, I) samples as the prior-hole control (ink coverage, distinct, rendered), 8 lerp strips of posterior means (a canvas dissolve), graph-decoder latency. Decision: A1 and A3 pass - fit the flow prior (arm 3, lfp-v1). A1 fails - run once more at c = 16 under a new run identity; a second failure stops the canvas line.

Criteria

criterionmeasurepass
A1VT - v9 0.0074 [0.0034, 0.0112]; reduction vs nearest 0.0039 [-0.0002, 0.0080]False
A2held-out KL 1851.1929 [1803.5245, 1900.3220] nats; beta at floor FalseTrue
A3sample - mu 0.0012 [-0.0021, 0.0045]True

Result (339 validation icons, IEEE float32 greedy decoding (TF32 off: matmul and cuDNN); pixel metrics at 72 px)

measurevalue
VT from mu, pixel error0.0810 [0.0760, 0.0862]
VT from one posterior sample0.0822 [0.0769, 0.0875]
v9 (parent), same icons, float320.0737 [0.0689, 0.0785]
nearest training render or mirror0.0849 [0.0795, 0.0902]
nearest training render, no mirrors0.0897 [0.0848, 0.0947]
z = 0 decode (control)0.1720 [0.1650, 0.1794]
blank canvas0.1720
icons VT beats nearest / beats v9191 / 130
exact reconstructions0.015
held-out KL per dimension0.357
N(0, I) samples distinct / rendered64 / 64 of 64
N(0, I) samples with ink < 0.100.266 (validation icons 0.021)
selected step12000 (fallback: False)

Resources

measurevalue
deviceNVIDIA GeForce RTX 4080
parameters9,038,402
train seconds3172
peak VRAM GiB4.304556369781494
graph decode ms per icon, batch 1, IEEE float321144.1
torch / CUDA2.14.0a0+4fdf77b940.nv26.08 / 13.4

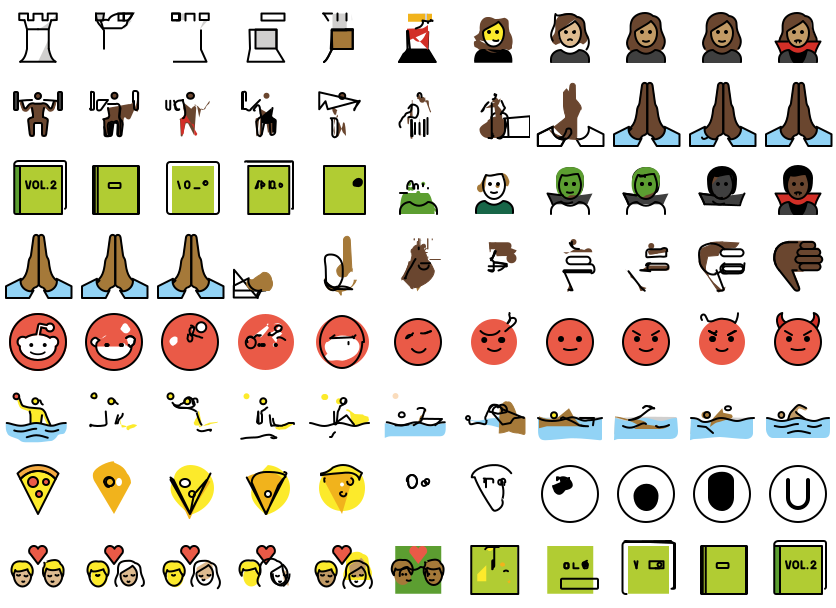
Sheets: reconstructions.png (reference, VT from mu, VT from a posterior sample, v9, nearest training render or mirror), interpolations.png (lerp of posterior means, a canvas dissolve), prior-samples.png (N(0, I), the prior-hole control).

State transitions

  1. running2026-09-29T15:48:24Z
  2. completed2026-09-29T16:44:12Z

Run record

Verbatim from runs/vt-v2-c16-0f4d5de-1497d4b5-47646604/run.yaml, the record committed before launch.

schema_version
2
run_id
vt-v2-c16-0f4d5de-1497d4b5-47646604
state
completed
planned_at
2026-09-29T15:48:24Z
hypothesis
A variational transcriber - v9 whose 18 x 18 stem grid passes through a per-cell Gaussian latent (c = 16 channels) held at a KL budget of C = 2,000 nats per icon - keeps v9's persistent spatial record of what is still undrawn and so reconstructs held-out icons from its posterior mean close to v9, while its latent is smooth at the posterior scale. Pass, on the first 339 validation icons, IEEE float32 (TF32 off) greedy decoding, 72 px pixel error, bootstrap intervals, all comparisons paired, requires A1 and A3; A2 is a collapse check. (A1) reconstruction from mu is non-inferior to v9 re-decoded in float32 on the same icons - the upper 95% bound of (VT - v9) is at most +0.015 - and beats the nearest training render or its mirror (every model trains with mirrors), the 95% interval on the reduction excluding zero. (A2) held-out KL within [0.8C, 1.2C] = [1,600, 2,400] nats per icon with beta above its floor of 1e-4; the controller enforces this band, so it detects collapse and is not evidence of anything else. (A3) decoding one posterior sample instead of mu costs at most 0.010 pixel error, paired mean. Reported without a criterion: the z = 0 decode, N(0, I) samples as the prior-hole control (ink coverage, distinct, rendered), 8 lerp strips of posterior means (a canvas dissolve), graph-decoder latency. Decision: A1 and A3 pass - fit the flow prior (arm 3, lfp-v1). A1 fails - run once more at c = 16 under a new run identity; a second failure stops the canvas line.
parent_run
r2s-full-v9-colour-621bc8e-b26ad95e-47646604
git_commit
0f4d5de77b0c00e335e523dca434c3a197ac7c5d
dirty_patch_sha256
7aca5c46e9225b04…
config_sha256
1497d4b55cfa80b3…
uncommitted_sources
config
configs/latent/vt-v2-c16.yaml
config_resolved
model
image_size
144
d_model
256
heads
8
encoder_layers
2
decoder_layers
6
feedforward
1024
dropout
0.1
metric
true
fourier
10
order
path
canvas
channels
16
budget_nats
2000
beta_initial
0.0001
beta_min
0.0001
beta_max
1.0
beta_rate
0.01
kl_ema_decay
0.9
band_low
0.8
band_high
1.2
log_variance_bias
-6.0
pca_icons
None
training
steps
30000
batch_size
32
learning_rate
0.0003
weight_decay
0.01
warmup_steps
500
seed
7001
eval_every
2000
eval_icons
64
train_icons
None
evaluate_on_train
false
augment_variants
0
augment_seed
9001
augment_mirror
0.5
augment_max_shift
48
augment_colour
0.1
augment_online
true
compose_probability
0.5
compose_parts
4
augment_original
0.1
loader_workers
16
extra_training
bf16
true
eval_icons
339
prior_samples
64
interpolation_pairs
8
interpolation_frames
9
non_inferiority_margin
0.015
sample_cost_margin
0.01
initialisation
parent_checkpoint
/home/dev/.cache/mojidiff/runs/r2s-full-v9-colour-621bc8e-b26ad95e-47646604/best.pt
parent_checkpoint_sha256
8bfedc8a7085b1bf…
parent_step
58000
pca_icons
2681
pca_cells
868644
pca_explained_variance
4
0.3973277208136002
8
0.5450375475430687
16
0.7067984697688607
32
0.8540104568007753
log_variance_bias
-6.0
pca_precision
IEEE float32 features (TF32 off), float64 moments
preflight
report
reports/latent/vt-v1-preflight.json
report_sha256
fbb9baf04924d66e…
chosen_channels
16
rule_outcome
declared fallback: vt-v1-74dfbd2-46380052-47646604 failed A1 at c = 8; rerun once at c = 16
fallback
run
vt-v1-74dfbd2-46380052-47646604
failed
A1
run_channels
8
rank_errors
rank_8
0.11636608914704993
rank_16
0.10885781893739477
dataset
pilot_config
configs/learning/openmoji-g1-geometric-gate-v16.yaml
cache_sha256
476466042da98d72…
train_icons
2681
evaluated_on
primary/validation
seed
7001
determinism
seeded; cuDNN and SDPA kernels not forced deterministic
model_parameters
9038402
command
.venv/bin/python -m mojidiff.learning.pixel_latent --config configs/latent/vt-v2-c16.yaml
outputs
run_dir
runs/vt-v2-c16-0f4d5de-1497d4b5-47646604
checkpoints
/home/dev/.cache/mojidiff/runs/vt-v2-c16-0f4d5de-1497d4b5-47646604
notes
completed_at
2026-09-29T16:44:12Z
resource
device
NVIDIA GeForce RTX 4080
torch_version
2.14.0a0+4fdf77b940.nv26.08
cuda_version
13.4
python_version
3.12.3
peak_vram_gib
4.304556369781494
train_seconds
3171.5166069259867
inference_ms_per_icon
1144.0655204933137
inference_p95_ms_per_icon
1144.4297150010243
icons_per_second
0.8740758130433006
decoder
fast_decode.GraphDecoder, IEEE float32 (TF32 off), batch 1, from a uint8 render (mu path)
decoder_calls
799
excludes
rasterising the output SVG
note
measured while other GPU work may be running
baselines
parent_v9_float32_pixel_error
0.07365292242874466
nearest_training_icon_pixel_error
0.0848698990662597
nearest_training_icon_pixel_error_without_mirrors
0.08973124639576185
prior_mean_decode_pixel_error
0.1720480552069557
blank_canvas_pixel_error
0.1720480552069557
note
v9 re-decoded here in IEEE float32 on the same icons; the nearest training icon searches training renders and their mirrors; all comparisons paired
result
icons
339
precision
IEEE float32 greedy decoding (TF32 off: matmul and cuDNN); pixel metrics at 72 px
reconstruction_pixel_error
0.08100594331468812, 0.07595325954395847, 0.08619624428514334
reconstruction_pixel_error_median
0.0749223381280899
posterior_sample_pixel_error
0.08219949751678554, 0.07691869020521833, 0.08752253197665953
parent_pixel_error
0.07365292242874466, 0.0689261002689255, 0.07848598195775747
nearest_training_icon_pixel_error
0.0848698990662597, 0.079514402055019, 0.09023761259991783
nearest_training_icon_pixel_error_without_mirrors
0.08973124639576185, 0.0848205749792233, 0.09466393787711656
prior_mean_decode_pixel_error
0.1720480552069557, 0.16502587235832153, 0.17943855658129604
latent_minus_prior_mean_error_reduction
0.09104211189226759, 0.08395800076272988, 0.09842899824819258
blank_pixel_error
0.1720480552069557
icons_vt_beats_nearest
191
icons_vt_beats_v9
130
exact_reconstruction_rate
0.014749262536873156
rendered_rate
1.0
held_out_kl_nats
1851.1929276277885, 1803.5244637998508, 1900.3219948467604
held_out_kl_nats_per_dimension
0.35709740116276784
prior_samples
count
64
distinct
64
rendered
64
ink_coverage_median
0.11651234567901235
fragment_rate_ink_below_0.10
0.265625
near_blank_rate_ink_below_0.02
0.0
validation_fragment_rate_ink_below_0.10
0.02064896755162242
role
N(0, I) prior-hole control, not a generator claim
interpolation
pairs
286, 250
54, 155
124, 257
154, 72
309, 145
206, 30
… and 2 more
frames
9
graph_decoder_agrees_with_greedy
render
true
prior_latent
true
criteria
A1
claim
reconstruction from mu is non-inferior to v9 (upper 95% bound of VT - v9 <= +0.015) and beats the nearest training render or its mirror (paired interval on the reduction above zero)
vt_minus_v9
0.0073530208859434705, 0.003399245347844843, 0.01118451675604809
reduction_vs_nearest_training_icon
0.003863955751571572, -0.00015545460099497245, 0.007969354758142935
pass
false
A2
claim
held-out KL within [1600, 2400] nats with beta above its floor (detects collapse only; the controller enforces the band)
held_out_kl_nats
1851.1929276277885, 1803.5244637998508, 1900.3219948467604
beta_at_floor
false
pass
true
A3
claim
decoding one posterior sample instead of mu costs at most 0.01 pixel error (paired mean)
sample_minus_mu
0.0011935542020974214, -0.0020579850431598633, 0.004513085034007453
pass
true
float32_flags
matmul_allow_tf32
false
cudnn_allow_tf32
false
float32_matmul_precision
highest
tf32_cublas_override_variable
1
selection
rule
lowest 64-icon bf16 greedy pixel error among evaluations with held-out KL in [1600, 2400] nats; else lowest overall
fallback_no_eval_in_band
false
step
12000
eval_pixel_error_mean
0.0767204573348863
held_out_kl_nats
1821.81494140625
beta
0.007177545591530315
selected_step
12000