MojiDiff

← experiments

vt-v3-d02-d05a169-ec3c4d8e-47646604

completed —

Hypothesis

A variational transcriber - the new final transcriber whose 18 x 18 stem grid passes through a per-cell Gaussian latent (c = 16 channels, chosen by the pre-flight) held at a KL budget of C = 2,000 nats per icon - reconstructs held-out icons from its posterior mean close to its parent while its latent is smooth at the posterior scale. Pass, on the first 339 validation icons, IEEE float32 (TF32 off) greedy decoding, 72 px pixel error, bootstrap intervals, all comparisons paired, requires A1 and A3; A2 is a collapse check. (A1) reconstruction from mu is non-inferior to the parent re-decoded in float32 on the same icons - the upper 95% bound of (VT - parent) is at most +0.015 - and beats the nearest training render or its mirror, the 95% interval on the reduction excluding zero. (A2) held-out KL within [0.8C, 1.2C] with beta above its floor. (A3) decoding one posterior sample instead of mu costs at most 0.010 pixel error, paired mean. Note: the parent was chosen as the best of four seeds on these validation icons, so its score is optimistic and non-inferiority is the harder half. Decision for the line (three seeds): at least two runs pass A1 and A3 - fit the flow prior; otherwise stop.

Visual output
interpolations
interpolations.png
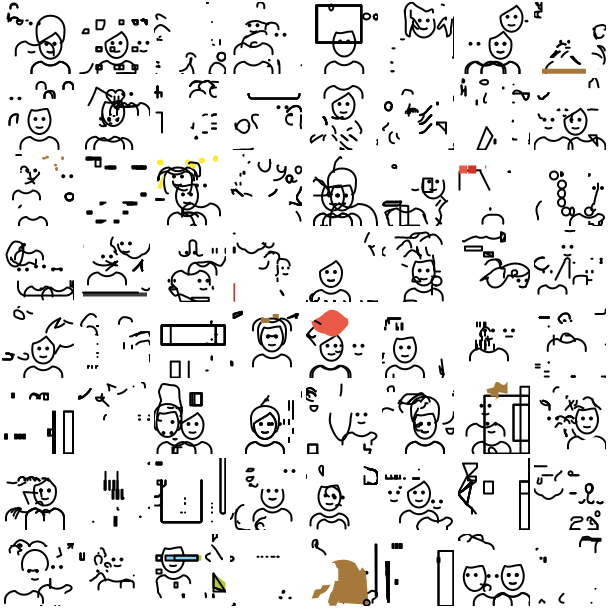
prior-samples
prior-samples.png
reconstructions
reconstructions.png

Written result

Hypothesis. A variational transcriber - the new final transcriber whose 18 x 18 stem grid passes through a per-cell Gaussian latent (c = 16 channels, chosen by the pre-flight) held at a KL budget of C = 2,000 nats per icon - reconstructs held-out icons from its posterior mean close to its parent while its latent is smooth at the posterior scale. Pass, on the first 339 validation icons, IEEE float32 (TF32 off) greedy decoding, 72 px pixel error, bootstrap intervals, all comparisons paired, requires A1 and A3; A2 is a collapse check. (A1) reconstruction from mu is non-inferior to the parent re-decoded in float32 on the same icons - the upper 95% bound of (VT - parent) is at most +0.015 - and beats the nearest training render or its mirror, the 95% interval on the reduction excluding zero. (A2) held-out KL within [0.8C, 1.2C] with beta above its floor. (A3) decoding one posterior sample instead of mu costs at most 0.010 pixel error, paired mean. Note: the parent was chosen as the best of four seeds on these validation icons, so its score is optimistic and non-inferiority is the harder half. Decision for the line (three seeds): at least two runs pass A1 and A3 - fit the flow prior; otherwise stop.

Criteria

criterionmeasurepass
A1VT - v9 0.0179 [0.0140, 0.0221]; reduction vs nearest 0.0027 [-0.0021, 0.0073]False
A2held-out KL 1840.5867 [1794.1798, 1888.6287] nats; beta at floor FalseTrue
A3sample - mu 0.0013 [-0.0022, 0.0047]True

Result (339 validation icons, IEEE float32 greedy decoding (TF32 off: matmul and cuDNN); pixel metrics at 72 px)

measurevalue
VT from mu, pixel error0.0821 [0.0772, 0.0871]
VT from one posterior sample0.0835 [0.0783, 0.0887]
v9 (parent), same icons, float320.0642 [0.0595, 0.0692]
nearest training render or mirror0.0849 [0.0795, 0.0902]
nearest training render, no mirrors0.0897 [0.0848, 0.0947]
z = 0 decode (control)0.1720 [0.1650, 0.1794]
blank canvas0.1720
icons VT beats nearest / beats v9187 / 81
exact reconstructions0.015
held-out KL per dimension0.355
N(0, I) samples distinct / rendered64 / 64 of 64
N(0, I) samples with ink < 0.100.109 (validation icons 0.021)
selected step2000 (fallback: False)

Resources

measurevalue
deviceNVIDIA B300 SXM6 AC
parameters9,038,402
train seconds1552
peak VRAM GiB4.3444905281066895
graph decode ms per icon, batch 1, IEEE float32737.5
torch / CUDA2.14.1+cu130 / 13.0

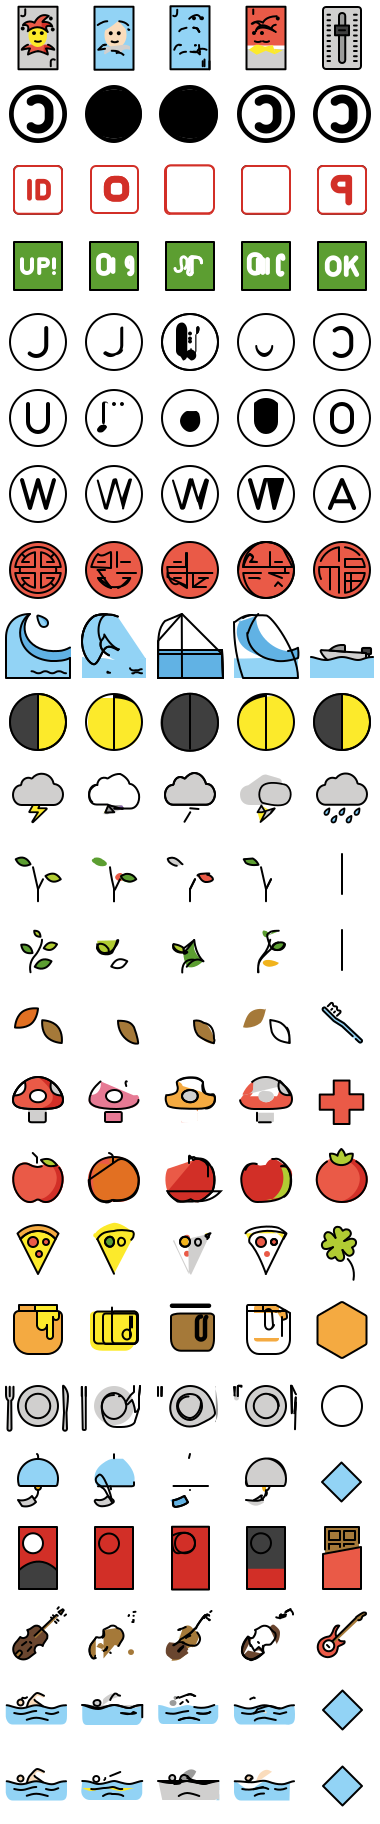
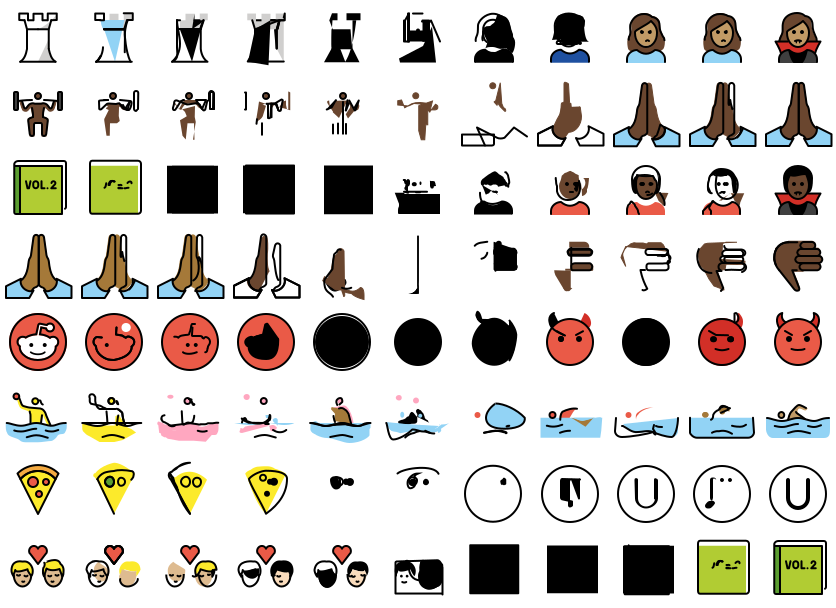
Sheets: reconstructions.png (reference, VT from mu, VT from a posterior sample, v9, nearest training render or mirror), interpolations.png (lerp of posterior means, a canvas dissolve), prior-samples.png (N(0, I), the prior-hole control).

State transitions

  1. running2026-10-30T23:25:38Z
  2. completed2026-10-30T23:55:13Z

Run record

Verbatim from runs/vt-v3-d02-d05a169-ec3c4d8e-47646604/run.yaml, the record committed before launch.

schema_version
2
run_id
vt-v3-d02-d05a169-ec3c4d8e-47646604
state
completed
planned_at
2026-10-30T23:25:38Z
hypothesis
A variational transcriber - the new final transcriber whose 18 x 18 stem grid passes through a per-cell Gaussian latent (c = 16 channels, chosen by the pre-flight) held at a KL budget of C = 2,000 nats per icon - reconstructs held-out icons from its posterior mean close to its parent while its latent is smooth at the posterior scale. Pass, on the first 339 validation icons, IEEE float32 (TF32 off) greedy decoding, 72 px pixel error, bootstrap intervals, all comparisons paired, requires A1 and A3; A2 is a collapse check. (A1) reconstruction from mu is non-inferior to the parent re-decoded in float32 on the same icons - the upper 95% bound of (VT - parent) is at most +0.015 - and beats the nearest training render or its mirror, the 95% interval on the reduction excluding zero. (A2) held-out KL within [0.8C, 1.2C] with beta above its floor. (A3) decoding one posterior sample instead of mu costs at most 0.010 pixel error, paired mean. Note: the parent was chosen as the best of four seeds on these validation icons, so its score is optimistic and non-inferiority is the harder half. Decision for the line (three seeds): at least two runs pass A1 and A3 - fit the flow prior; otherwise stop.
parent_run
r2s-cur-d02-s120k-seed2-53b3108-46294452-47646604
git_commit
d05a169267a244348bec4e22d200735adb0092b5
dirty_patch_sha256
config_sha256
ec3c4d8e721b7260…
uncommitted_sources
config
configs/latent/vt-v3-d02.yaml
config_resolved
model
image_size
144
d_model
256
heads
8
encoder_layers
2
decoder_layers
6
feedforward
1024
dropout
0.2
metric
true
fourier
10
order
path
sources
0
canvas
channels
16
budget_nats
2000
beta_initial
0.0001
beta_min
0.0001
beta_max
1.0
beta_rate
0.01
kl_ema_decay
0.9
band_low
0.8
band_high
1.2
log_variance_bias
-6.0
pca_icons
None
training
steps
30000
batch_size
32
learning_rate
0.0003
weight_decay
0.01
warmup_steps
500
seed
7002
eval_every
2000
eval_icons
64
train_icons
None
evaluate_on_train
false
augment_variants
0
augment_seed
9002
augment_mirror
0.5
augment_max_shift
48
augment_colour
0.1
augment_online
true
compose_probability
0.5
compose_parts
4
augment_original
0.1
loader_workers
16
extra_training
bf16
true
eval_icons
339
prior_samples
64
interpolation_pairs
8
interpolation_frames
9
non_inferiority_margin
0.015
sample_cost_margin
0.01
initialisation
parent_checkpoint
/home/eai-jdkxz/eai-team11/mojidiff/cache/runs/r2s-cur-d02-s120k-seed2-53b3108-46294452-47646604/best.pt
parent_checkpoint_sha256
38daeca4dd27fb4c…
parent_step
64000
pca_icons
2681
pca_cells
868644
pca_explained_variance
4
0.3929850127433201
8
0.519129026163516
16
0.6671638008956701
32
0.8159108283748467
log_variance_bias
-6.0
pca_precision
IEEE float32 features (TF32 off), float64 moments
preflight
report
reports/latent/vt-v3-d02-preflight.json
report_sha256
92ca25fe9135087a…
chosen_channels
16
rule_outcome
rank-8 error 0.1230 > 0.12, rank-16 0.0951 <= it: c = 16
fallback
None
rank_errors
rank_8
0.12304223270621151
rank_16
0.09505583022837527
dataset
pilot_config
configs/learning/openmoji-g1-geometric-gate-v16.yaml
cache_sha256
476466042da98d72…
train_icons
2681
evaluated_on
primary/validation
seed
7002
determinism
seeded; cuDNN and SDPA kernels not forced deterministic
model_parameters
9038402
command
.venv/bin/python -m mojidiff.learning.pixel_latent --config configs/latent/vt-v3-d02.yaml
outputs
run_dir
runs/vt-v3-d02-d05a169-ec3c4d8e-47646604
checkpoints
/home/eai-jdkxz/eai-team11/mojidiff/cache/runs/vt-v3-d02-d05a169-ec3c4d8e-47646604
notes
completed_at
2026-10-30T23:55:13Z
resource
device
NVIDIA B300 SXM6 AC
torch_version
2.14.1+cu130
cuda_version
13.0
python_version
3.12.3
peak_vram_gib
4.3444905281066895
train_seconds
1552.1720755679999
inference_ms_per_icon
737.4747749709059
inference_p95_ms_per_icon
737.9868610296398
icons_per_second
1.3559785825073827
decoder
fast_decode.GraphDecoder, IEEE float32 (TF32 off), batch 1, from a uint8 render (mu path)
decoder_calls
541
excludes
rasterising the output SVG
note
measured while other GPU work may be running
baselines
parent_v9_float32_pixel_error
0.06424614373597162
nearest_training_icon_pixel_error
0.0848698990662597
nearest_training_icon_pixel_error_without_mirrors
0.08973124639576185
prior_mean_decode_pixel_error
0.1720480552069557
blank_canvas_pixel_error
0.1720480552069557
note
v9 re-decoded here in IEEE float32 on the same icons; the nearest training icon searches training renders and their mirrors; all comparisons paired
result
icons
339
precision
IEEE float32 greedy decoding (TF32 off: matmul and cuDNN); pixel metrics at 72 px
reconstruction_pixel_error
0.08214886323926603, 0.07723369739777913, 0.087108976889566
reconstruction_pixel_error_median
0.07478667795658112
posterior_sample_pixel_error
0.08346931096375851, 0.07834459422314612, 0.08867381948882928
parent_pixel_error
0.06424614373597162, 0.05945421143144472, 0.06923222867580506
nearest_training_icon_pixel_error
0.0848698990662597, 0.079514402055019, 0.09023761259991783
nearest_training_icon_pixel_error_without_mirrors
0.08973124639576185, 0.0848205749792233, 0.09466393787711656
prior_mean_decode_pixel_error
0.1720480552069557, 0.16502587235832153, 0.17943855658129604
latent_minus_prior_mean_error_reduction
0.08989919196768968, 0.0832920048036398, 0.09672539426262111
blank_pixel_error
0.1720480552069557
icons_vt_beats_nearest
187
icons_vt_beats_v9
81
exact_reconstruction_rate
0.014749262536873156
rendered_rate
1.0
held_out_kl_nats
1840.5866528176277, 1794.1798219483862, 1888.628716482877
held_out_kl_nats_per_dimension
0.3550514376577214
prior_samples
count
64
distinct
64
rendered
64
ink_coverage_median
0.1636766975308642
fragment_rate_ink_below_0.10
0.109375
near_blank_rate_ink_below_0.02
0.0
validation_fragment_rate_ink_below_0.10
0.02064896755162242
role
N(0, I) prior-hole control, not a generator claim
interpolation
pairs
286, 250
54, 155
124, 257
154, 72
309, 145
206, 30
… and 2 more
frames
9
graph_decoder_agrees_with_greedy
render
true
prior_latent
true
criteria
A1
claim
reconstruction from mu is non-inferior to v9 (upper 95% bound of VT - v9 <= +0.015) and beats the nearest training render or its mirror (paired interval on the reduction above zero)
vt_minus_v9
0.017902719503294397, 0.01395112202815943, 0.022138037989721734
reduction_vs_nearest_training_icon
0.0027210358269936764, -0.0020835074398706413, 0.0072583821646631675
pass
false
A2
claim
held-out KL within [1600, 2400] nats with beta above its floor (detects collapse only; the controller enforces the band)
held_out_kl_nats
1840.5866528176277, 1794.1798219483862, 1888.628716482877
beta_at_floor
false
pass
true
A3
claim
decoding one posterior sample instead of mu costs at most 0.01 pixel error (paired mean)
sample_minus_mu
0.0013204477244924896, -0.002161467053489979, 0.004663091841323616
pass
true
float32_flags
matmul_allow_tf32
false
cudnn_allow_tf32
false
float32_matmul_precision
highest
tf32_cublas_override_variable
None
selection
rule
lowest 64-icon bf16 greedy pixel error among evaluations with held-out KL in [1600, 2400] nats; else lowest overall
fallback_no_eval_in_band
false
step
2000
eval_pixel_error_mean
0.0778899564902531
held_out_kl_nats
1821.489501953125
beta
0.010261688755738897
selected_step
2000